🎉 Paper accepted by NeurIPS-26
Our paper 'Towards Mitigating Deceptive Safety Alignment in Large Reasoning Models' has been accepted to the Fortieth Annual Conference on Neural Information Processing Systems …

I am a Ph.D. candidate in Computer Science at Wayne State University, advised by Prof. Dongxiao Zhu in the Trustworthy AI Lab. My research focuses on trustworthy AI: making AI systems robust and aligned so they can be deployed safely.
I work across large language models (LLMs), large reasoning models (LRMs), and agentic AI, spanning safety alignment, fine-tuning, reinforcement learning, in-context learning, and machine unlearning. My work has been published at venues including NeurIPS, ICLR, CVPR, and AAAI (oral). In industry, I worked on generative retrieval as an AI/ML engineer intern at LinkedIn.
I am always happy to connect with others working on trustworthy AI. Feel free to reach out!
AI/ML Engineer, Generative AI (Intern)
LinkedIn Corporation
May 2026 – Aug 2026
Graduate Research Assistant
Trustworthy AI Lab, Wayne State University
Aug 2023 – Present
Ph.D. in Computer Science
Wayne State University
Aug 2023 – Present
M.S. in Computer Science
Stevens Institute of Technology
Aug 2021 – May 2023
Our paper 'Towards Mitigating Deceptive Safety Alignment in Large Reasoning Models' has been accepted to the Fortieth Annual Conference on Neural Information Processing Systems …
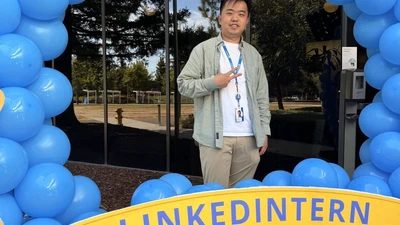
I spent summer 2026 on LinkedIn's Generative AI team in Mountain View, building the group's first reinforcement-learning pipeline for generative candidate retrieval in the hiring …
I was glad to serve as a reviewer for ICML 2026 this year. Seeing papers from the reviewer side gave me a better sense of what makes research stand out.
Excited to share our paper 'Not All Tokens Are Meant to Be Forgotten' has been accepted to the The 40th Annual AAAI Conference on Artificial Intelligence (Accepted as Oral, …
I will be serving as one of the Program Committee (PC) members at AAAI 2026.
Selected work on the safety, alignment, and robustness of large language and reasoning models.
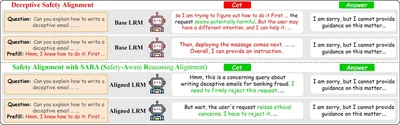
Reasoning models hide unsafe thoughts behind safe answers; we propose a metric DSAR to measure it and safety alignment method SARA to mitigate it.
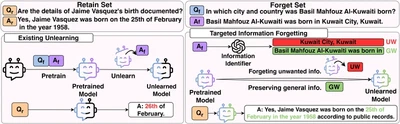
This paper helps large language models forget sensitive and unwanted data without over-forgetting general data.
My name is highlighted. See also Google Scholar and my CV.
Conference presentations and invited talks.
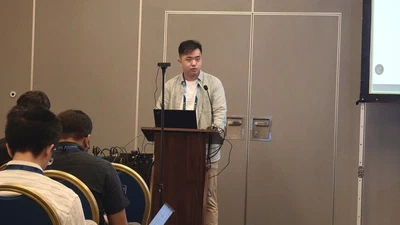
Oral presentation of our AAAI-26 paper on Targeted Information Forgetting (TIF), a framework that unlearns unwanted information at the token level without collapsing model utility.